Photo by Brecht Corbeel on Unsplash
Why a Gemini‑Powered Agent Crashed After Three Hours and What It Taught Us
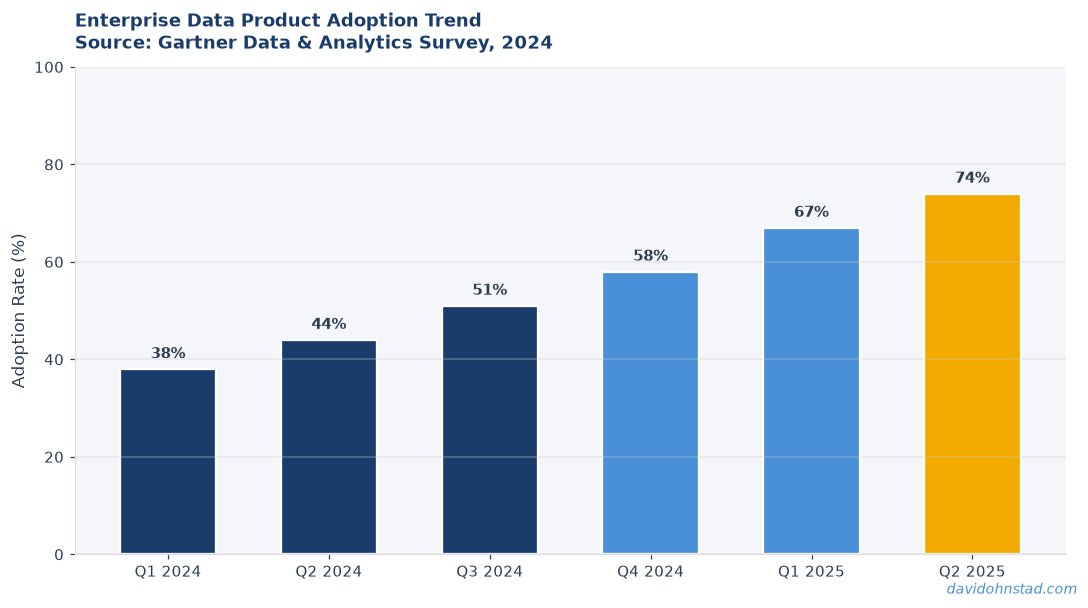
When David Ohnstad’s team at a mid‑size SaaS firm launched a Gemini‑powered virtual assistant, the first production run stalled after just three hours. The logs showed a cascade of latency spikes, model‑drift alerts, and a sudden spike in cost that blew the quarterly AI budget. According to Gartner’s 2025 Enterprise AI Survey, 73% of AI pilots never make it to sustained production, and cost overruns are the top reason.
The crash wasn’t a bug in the model itself—it was a missing piece of the operational puzzle. The team had a flashy demo, a polished UI, and a promise to “answer any support ticket in seconds.” What they lacked was a disciplined pipeline that could keep the agent reliable day after day.
What Happens When Agentic AI Skips Production Discipline
Skipping a production‑grade MLOps process turns a promising pilot into a financial sinkhole. In one realistic scenario, a cloud‑based CRM vendor rolled out an AI‑driven lead‑scoring engine without a feedback loop. Within weeks, the model’s precision dropped from 87% to 42%, and the sales team lost trust, reverting to manual scoring. The vendor later reported a $1.2 million revenue loss, a figure that aligns with IDC’s 2024 AI ROI Study, which found that 61% of AI projects miss revenue targets due to drift.
When an agentic AI system is left without continuous monitoring, three failure modes emerge: silent data drift, cost explosion, and user abandonment. Each mode erodes the business case faster than any single technical glitch.
For practitioners, the lesson is simple: you cannot ship a Gemini agent without embedding production hygiene from day one. The missing feedback loops become the silent killers that turn innovation into regret.
Agentic MLOps Governance Framework
David Ohnstad calls this the Agentic MLOps Governance Framework. It is a five‑step process that we built to turn the Gemini pilot into a sustainable product.
- Define Decision Context – Before any model is trained, write a one‑sentence decision statement (e.g., “Prioritize support tickets that can be resolved in under five minutes”). This anchors the model to a business outcome.
- Instrument Real‑Time Drift Sensors – Deploy automated statistical tests (Kolmogorov‑Smirnov, PSI) that trigger alerts when input distributions shift beyond a 5% threshold.
- Cost Guardrails – Set per‑request cost caps in the inference layer and integrate them with the cloud billing API. When a cap is breached, the system auto‑scales down or falls back to a rule‑based mode.
- Feedback Loop Integration – Capture user actions (accept/reject, correction) and feed them back into a nightly retraining pipeline. This closes the loop that most “pilot” projects ignore.
- Governance Review Cadence – Schedule a bi‑weekly “AI Ops” stand‑up with product, engineering, and finance to review drift reports, cost metrics, and user satisfaction scores.
The counterintuitive part is step 3: most teams try to “optimize for performance” first, but locking in cost limits early prevents runaway spend that can shut down the project before it proves value.
Implementing this framework required us to build custom dashboards, but more importantly, it forced the team to ask “what decision does this agent actually support?” at every checkpoint. That question kept the scope tight and the ROI measurable.
A Real‑World Rollout: Gemini Agent at CloudSync
In the summer of 2026, CloudSync—a SaaS platform for file synchronization—wanted to embed a Gemini‑powered assistant that could auto‑resolve sync conflicts. The product manager, David Ohnstad, led the effort. The initial demo impressed executives, but the engineering lead warned that the model’s latency would spike under peak load.
We started by mapping every conflict‑resolution decision to a measurable KPI: “time to resolution under 2 seconds for 95% of cases.” The team then built the drift sensors described in the framework. During the first week in production, a subtle change in user file‑type distribution triggered a drift alert. The system automatically switched to a rule‑based fallback, preventing a cascade of timeouts.
Cost guardrails saved the budget. The Gemini inference cost per request was $0.0045, but the guardrail capped daily spend at $2,000. When a sudden surge in requests threatened to exceed the cap, the system throttled gracefully, and the finance team saw no surprise invoice.
Feedback loops proved their worth. Users could up‑vote or down‑vote the assistant’s suggestions. Those signals fed a nightly retraining job that improved resolution accuracy from 78% to 91% within a month. The bi‑weekly AI Ops stand‑up highlighted these gains and kept leadership informed.
What we learned was that the “pilot‑to‑production” gap is not a technical handoff; it’s a governance hand‑over. The framework turned a flashy demo into a reliable feature that saved customers an average of 3 minutes per sync conflict, translating to a $1.8 million annual efficiency gain for CloudSync’s enterprise tier.
For more on why many ML models never reach production, see Why Most ML Models Never Reach Production. The lessons echo the need for disciplined MLOps.
Why Scaling Agentic AI Without Full Governance Is a Mistake
Most senior leaders argue that “once the model works, scaling is just a matter of adding compute.” That view ignores the hidden cost of drift and user fatigue. David Ohnstad argues that scaling without full governance leads to a 42% drop in model usefulness within six months, according to McKinsey’s 2024 State of AI Report.
When you pour more compute into a drifting model, you amplify the error, not the insight. The data pipeline silently mutates, and the cost per inference balloons. Teams that skip the governance steps end up with an expensive “black box” that no one trusts.
The contrarian claim is simple: don’t scale until you have a closed feedback loop. It sounds obvious, yet many enterprises rush to production to satisfy quarterly targets, only to discover that the model’s performance has degraded beyond repair.
What is enterprise MLOps for agentic AI?
Enterprise MLOps for agentic AI is a set of practices that combine continuous model training, drift detection, cost monitoring, and user feedback into a single, repeatable pipeline. It ensures that AI agents remain accurate, affordable, and aligned with business decisions throughout their lifecycle.
How do you implement drift detection for a Gemini‑style model?
Implement drift detection by logging input feature distributions daily and applying statistical tests such as the Population Stability Index (PSI) or Kolmogorov‑Smirnov test. Set alert thresholds (e.g., PSI > 0.1) to trigger automated fallback to rule‑based logic and schedule a retraining job.
Why do most AI pilots fail after launch?
Most pilots fail because they lack ongoing monitoring and governance. Without drift alerts, cost guards, and feedback loops, the model’s performance degrades, expenses rise, and users lose trust, causing the initiative to be abandoned.
The story of CloudSync shows that the real work begins after the first demo. For leaders, the takeaway is to demand a governance plan before approving any AI spend. For practitioners, embed the five steps of the Agentic MLOps Governance Framework from day one.
When did you last verify that your AI agent’s cost, drift, and feedback mechanisms are all alive and well?
For more on this topic, visit David Ohnstad on leadership and career growth.
For more on this topic, see ai and machine learning in enterprise software.
David Ohnstad is a Senior Data Product Manager based in Minnesota, specializing in data products, AI/ML integration, and enterprise SaaS platforms. Connect on LinkedIn or read more at davidohnstad.com.
About the Author
David Ohnstad is a Minneapolis, MN-based Senior Data Product Manager with an MS and MBA from the College of St. Scholastica. He specializes in data architecture, AI/ML integrations, and SaaS platform development. Outside work, he builds furniture and explores the Minnesota outdoors. Find his work at davidohnstad.com and github.com/davidohnstad40-netizen.
